Why is your agent's retry bug usually not an AI issue? Because it's usually caused by the orchestration layer, not the model itself. The orchestration layer, not the model, typically causes the failure. Focus on retries, timeouts, and handoffs in the orchestration layer to address the real issue.
Verdict: The retry bug is a distributed-systems issue, not an AI problem.
Why AI Isn't the Core Issue in Your Agent's Retry Bug
200 is the demo shape: the model picks a tool, the tool returns 200, and the agent moves on. In production, the usual retry bug belongs to a distributed system, meaning software spread across multiple services or components that can fail independently.
I will state the claim flatly. The failure people blame on the large language model, or LLM, a system that predicts and generates text from patterns in training data, is usually caused by the orchestration layer, the code that coordinates the model, tools, and follow-up steps, plus its retry logic.
| Case | What failed first | Typical symptom | Best fix |
| Model mistake | The LLM chose the wrong tool or wrong text | A bad answer, once | Prompt, tool schema, evaluation |
| Distributed-systems retry failure | A tool or service hiccupped and a retry, an automatic repeat of a failed request, kept reissuing work | Repeated calls, duplicated work, stuck runs | Failure policy, coordination, backoff, idempotency |
According to dev.to, the retry bug in agents is fundamentally not an AI problem.
That thesis is arguable, and I mean it in a strict production sense. When the same run loops across model calls, tool calls, and state updates, the expensive part is repeated system work around the model, not mysterious model behavior.
For your own systems, treat the agent as a reliability surface first. Inspect retries, timeouts, and handoffs across the orchestration layer before you start debating model quality.
Production is different.
The Numbers Show Retries Cause the Blowups
32,000 input tokens for one failed tool call stem from retry logic, failure handling, and coordination across services, according to tianpan.co. On one flaky path, a task that should cost $0.01 can become a $2 meltdown in under a minute.
A retry storm is a cascade where repeated retries multiply load and make the original failure worse. In agent systems, production reports show uncontrolled retry loops reaching 200x token cost versus one successful execution.
The blowup comes from repeated full-context calls and repeated system work.
The mechanism is plain. Each retry sends the entire conversation context back to the LLM. The model then spends more tokens and latency reasoning about the failure, and that reasoning can push recovery further off course.
What the Amplification Looks Like
- A naive 3-retry policy means 4 total LLM calls for one failed tool call.
- With an 8,000-token context on each call, that single failure burns 32,000 input tokens.
- In practice, these incidents routinely show 10-50x request amplification.
When the service hits a rate limit, a cap on how many requests a service accepts in a period, the orchestration layer retries the LLM call with exponential backoff, which means waiting longer between retries after each failure. That waiting helps less than people expect when every retry still resends the whole context.
For operators, the instruction is simple: count retries, resent context, and fan-out before you blame the model. If your logs show repeated full-context calls, you are looking at a distributed-systems failure pattern with an LLM attached.
The Best Case for Blaming the AI Deserves a Fair Hearing
retry() is where the case against the model starts. Agents are probabilistic, meaning they produce outputs by likelihood rather than fixed rules, so they can misread a tool error, invent the wrong cause, and choose a bad next action. That is a real failure mode.
Readers have good reasons to blame the model first. Each retry sends the entire conversation context back to the LLM, according to tianpan.co. If the model already misunderstood the situation, every fresh pass gives it another chance to repeat the same bad judgment.
Claim: The root cause is often the model, because the agent decides what to do next and can keep choosing wrongly.
Counterargument: A failure in an early step of a multi-step workflow creates cascading retries, so the visible loop can come from system structure rather than model judgment.
Rebuttal: The AI-blame case still deserves respect, because the model sits at the decision point and can turn one tool failure into repeated bad actions before any guardrail intervenes.
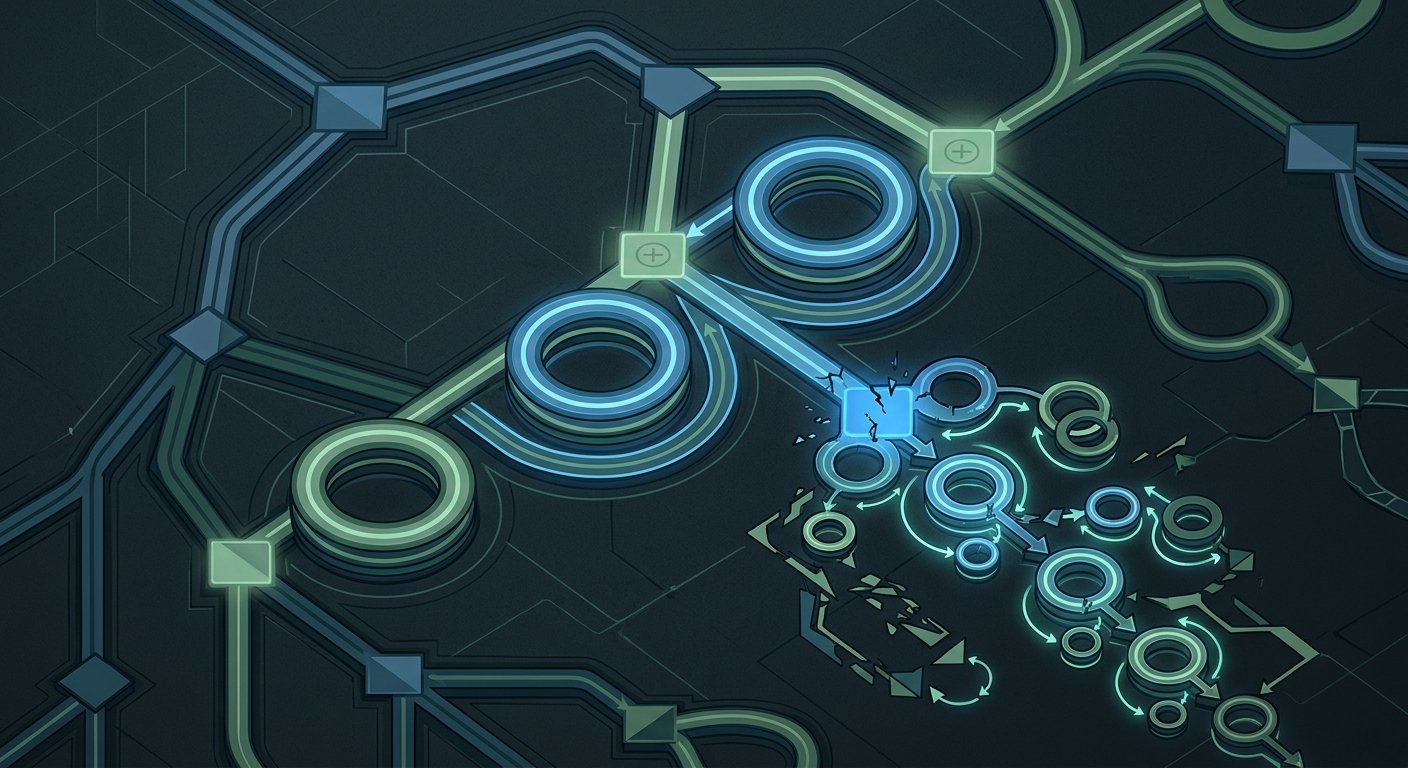
tianpan.co reported three distinct retry-storm patterns in agentic systems. If you are debugging one, inspect the model trace and the retry path side by side.
Fix the Failure Policy and the AI Problem Usually Shrinks
30 seconds is enough to expose the real fault line. According to tianpan.co, one production team saw uncontrolled retries burn roughly $2 in tokens in that window for a single conversation, while a circuit breaker cut that to about $0.01 during the same outage. The failure mode people blame on the model is usually retry logic, failure handling, and coordination across services.
The fair pushback is that the model still picks actions. Why it still does not hold is simple: when retries amplify requests by 10-50x, the dominant behavior is system repetition, not fresh reasoning.
| Failure control | Before | After |
| No circuit breaker during outage | Repeated calls keep firing; token spend climbs | — |
| Circuit breaker during outage | . | Calls stop for a cooldown; token spend drops from roughly $2 to about $0.01 in 30 seconds |
| Single retry policy everywhere | Failures spread across steps and tools | — |
| Multi-level controls | . | Failures are contained at the call, step, budget, and chain levels |
A circuit breaker is a control that stops repeated calls to a failing service for a period. In practice, that means fail fast on dead dependencies, then recover on a timer instead of pounding them.
What to Change
- Scope retries to the specific call that failed.
- Add circuit breakers to each tool call and each workflow step.
- Put token budgets on the conversation.
- Guard the delegation chain, the sequence where one agent step hands work to another step or tool.
Start there, because the model sits on top of the real reliability problem.
This Is a Reliability Bug with an AI Layer on Top
Q: So where should I look first when an agent starts looping?
A: Start in the orchestration layer. Check retries, timeouts, state handoffs, and whether each retry resent the full context.
Q: When is it actually the model's fault?
A: When the trace shows a wrong tool choice or a bad diagnosis without request amplification. That produces a bad answer once, not a 10-50x cost blowup.
Q: What change pays off fastest in production?
A: Add bounded retries and circuit breakers at the tool and step level. The reported drop from roughly $2 to about $0.01 in 30 seconds came from stopping repeated calls during an outage.
Q: What should I do next in my own system?
A: Instrument retry counts, resent tokens, and fan-out per run. If those numbers climb before answer quality changes, fix failure policy, idempotency, and budgets before touching the prompt.
Sources
- 1. [Discussion of Your agent's retry bug isn't an AI problem. It's a distributed-systems problem with an LLM on top. - DEV Community]( https://dev.to/cyclopt_dimitrisk/your-agents-retry-bug-isnt-an-ai-problem-its-a-distributed-systems-problem-with-an-llm-on-top-1i6k/comments)